A client once reached out fairly worried because several new service pages they'd added weeks earlier still weren't showing up on Google at all — not ranking poorly, just completely absent from search results. The pages were live, properly written, linked from the main menu. Nothing was obviously broken. What turned out to be missing was much quieter than that: there was no XML sitemap telling Google those pages existed in the first place, and the site's internal linking wasn't strong enough on its own to get them discovered quickly.
This is a fairly common situation, and it's exactly the kind of problem an XML sitemap exists to prevent. It's one of those technical SEO basics that's easy to overlook precisely because, when it's working properly, nothing visible happens — pages just get found and indexed the way they're supposed to. It's only when it's missing, broken, or outdated that the problem becomes obvious, usually as "why isn't this page showing up on Google."
What Is an XML Sitemap?
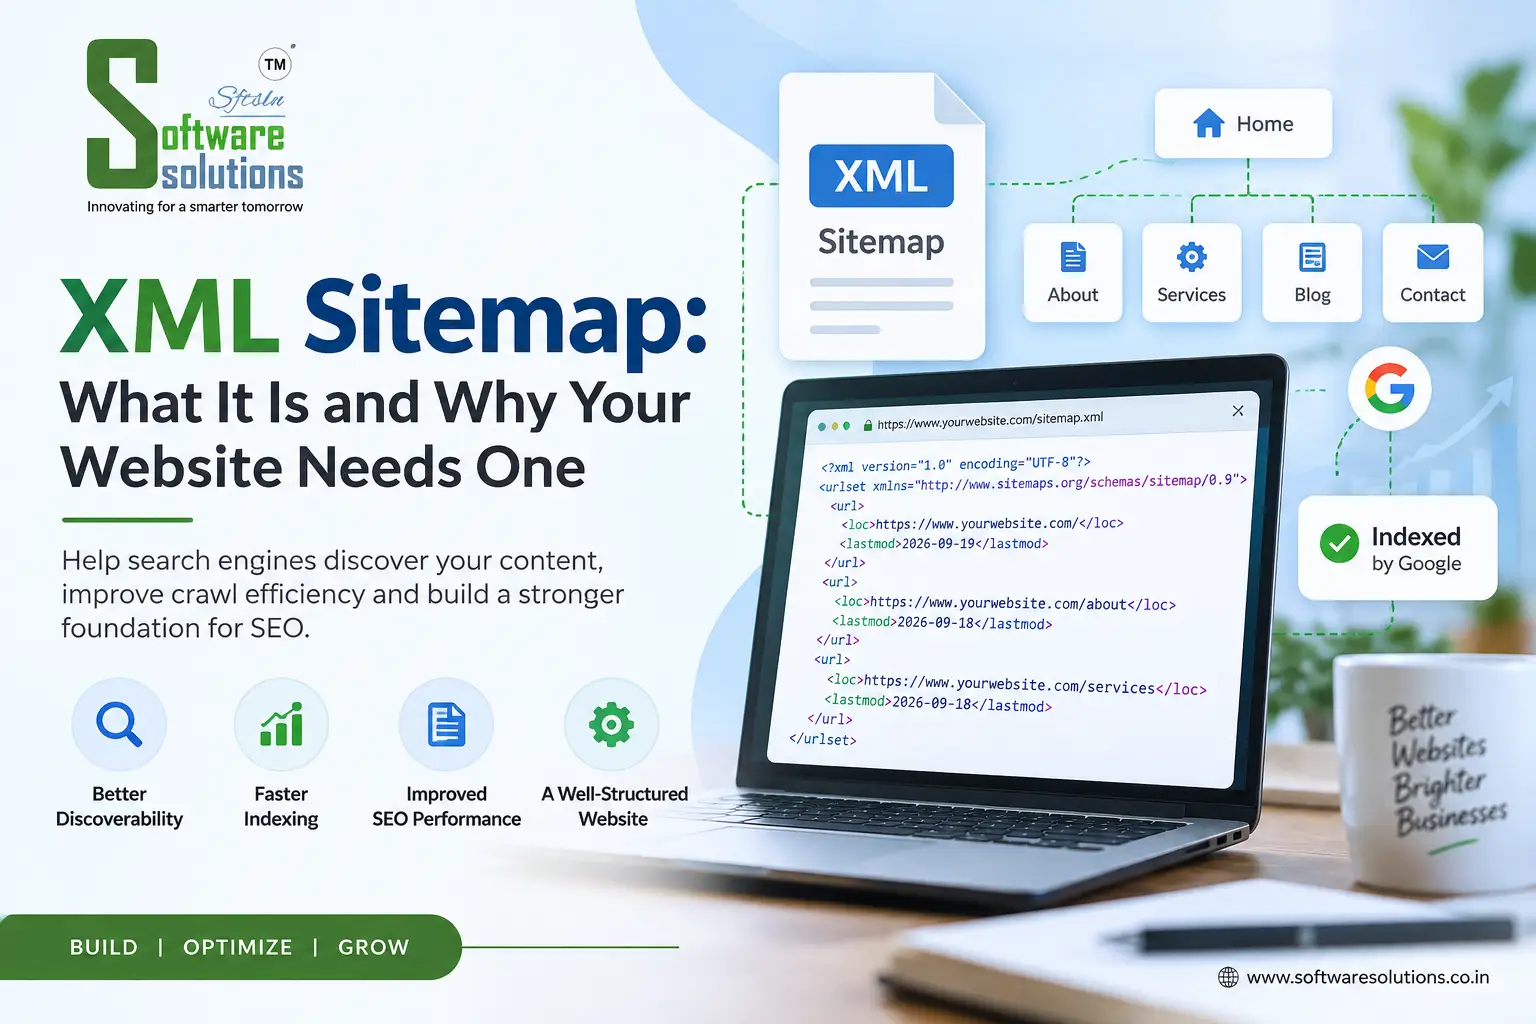
An XML sitemap is a structured file, written in XML format, that lists the URLs on a website you want search engines to know about. Think of it as a directory you hand directly to a search engine, rather than relying entirely on it to stumble across every page naturally through links.
It's not meant for human visitors — nobody browses a sitemap.xml file the way they'd browse a normal webpage. It's built specifically for search engine crawlers, giving them a clear, direct list of URLs, along with some optional extra information about each one, like when it was last updated.
How Does an XML Sitemap Work?
To understand why a sitemap matters, it helps to separate two things that often get conflated: crawling and indexing. Crawling is the process where a search engine's bot visits pages, following links from one to another, to discover what exists. Indexing is the separate step where a search engine actually processes and stores a page's content, making it eligible to appear in search results.
An XML sitemap primarily supports the first step — discovery. It gives a crawler a direct list of URLs to check, rather than relying purely on it following internal and external links to eventually stumble onto every page. This matters more than people often assume, particularly for pages that aren't well-connected through internal links, or for sites that are large, complex, or frequently changing.
It's worth being precise here: submitting a sitemap does not force indexing. It's an invitation and a discovery aid, not a guarantee. A search engine can still choose not to index a page listed in a sitemap, for reasons related to content quality, duplication, or technical issues elsewhere on the page.
Why Does Your Website Need an XML Sitemap?
Not every website needs a sitemap equally urgently, but there are specific situations where it genuinely matters:
Large websites. A site with hundreds or thousands of pages makes it much easier for a search engine to reliably discover everything when there's a direct, structured list available, rather than relying entirely on crawling behavior working perfectly across a large, complex link structure.
New websites. A newly launched site often has few or no external links pointing to it yet, and search engines may not have found it through crawling on their own. A submitted sitemap gives a new site a more direct path to initial discovery.
Websites with complex structures. Sites where certain pages are buried several clicks deep, or where internal linking doesn't naturally connect every page well, benefit from a sitemap as a backup discovery method.
Frequently updated websites. Sites that regularly publish new content — blogs, e-commerce catalogs, service listings — benefit from a sitemap that reflects those additions promptly, rather than waiting for organic crawling to catch up.
Dynamically generated websites. Sites built on a CMS or custom application, where pages are generated from a database rather than existing as static files, particularly benefit from a sitemap that's generated the same dynamic way — updating automatically as content changes, rather than requiring manual maintenance.
A small, simple website with a handful of well-linked pages may genuinely function fine without one. But for most active business websites, a properly maintained sitemap is a reasonable, low-effort safeguard rather than an unnecessary extra.
XML Sitemap and SEO: What Is the Connection?
This is worth addressing directly, because it's a common source of confusion. An XML sitemap helps with discovery — it makes it easier and faster for search engines to find the pages that should be indexed. What it does not do is directly improve rankings, fix content quality issues, or force pages to be indexed regardless of their actual quality or technical condition.
A sitemap full of thin, low-quality, or duplicate pages won't help those pages rank — if anything, it can waste a search engine's attention on pages that were never going to perform well anyway. The real SEO value of a sitemap is making sure your genuinely good, indexable pages get found promptly and reliably. Everything after that — whether they actually rank well — still depends on the usual factors: content quality, site structure, technical SEO, and internal linking.
What Should Be Included in an XML Sitemap?
A well-maintained sitemap should generally include:
- Canonical URLs — the single, preferred version of each page, particularly important on sites where the same content might be reachable through more than one URL
- Indexable pages — pages you actually want to appear in search results, not pages deliberately excluded from indexing
- Important website URLs — core pages like your homepage, main service or product pages, and key content
- A lastmod value where appropriate — indicating when a page was last meaningfully updated, which can help search engines prioritize re-crawling
It should generally exclude:
- Redirected URLs — old URLs that now redirect elsewhere shouldn't be listed as if they were the current, canonical destination
- 404 or broken pages — obviously, since these don't lead anywhere useful for a crawler to process
- Noindex pages — pages deliberately marked to be excluded from search results shouldn't also be listed in a sitemap, since that sends a contradictory signal
- Duplicate URLs — the same content reachable through multiple URL variations should only have its one canonical version listed
- Irrelevant parameter or filter URLs — common on e-commerce or filtered listing pages, where dozens of URL variations can exist for essentially the same content, cluttering a sitemap with little real value
A common mistake we see is a sitemap that simply lists every URL a site technically generates, without this kind of filtering — which ends up diluting the sitemap's usefulness rather than improving it.
XML Sitemap vs HTML Sitemap: What's the Difference?
These two are easy to mix up by name, but they serve genuinely different audiences:
| XML Sitemap | HTML Sitemap | |
|---|---|---|
| Built for | Search engine crawlers | Human visitors |
| Format | Structured XML file | Normal, viewable webpage |
| Purpose | Helps search engines discover URLs | Helps visitors navigate the site |
| Visibility | Not meant to be browsed by people | Fully visible in the site's normal navigation |
| Typical location | /sitemap.xml | A page linked from the site menu or footer |
Some sites benefit from having both — the XML version supporting technical discovery, and an HTML version genuinely helping visitors find content, particularly on larger sites with many sections.
How to Create an XML Sitemap
There are a few common approaches, depending on how a site is built:
CMS-generated sitemaps. Most modern content management systems, including popular ones like WordPress, can generate and maintain a sitemap automatically, often through a built-in feature or a widely used plugin, updating it as content is added or changed.
SEO plugins or tools. Dedicated SEO plugins frequently include sitemap generation as part of a broader feature set, alongside things like meta tag management and structured data.
Custom or dynamic generation. For custom-built web applications — which is common for businesses with specific functionality beyond what a standard CMS offers — the sitemap is typically generated programmatically from the site's own database, so it stays accurate as pages are added or removed.
Manual creation for small sites. A small, simple site with relatively few, stable pages can reasonably have a manually written sitemap, since the maintenance burden is low.
A basic XML sitemap follows a fairly simple, standard structure:
xml
<?xml version="1.0" encoding="UTF-8"?> <urlset xmlns="http://www.sitemaps.org/schemas/sitemap/0.9"> <url> <loc>https://example.com/</loc> <lastmod>2026-09-01</lastmod> </url> <url> <loc>https://example.com/services</loc> <lastmod>2026-08-15</lastmod> </url> </urlset>Each <url> entry contains at minimum a <loc> tag with the page's canonical URL, and optionally a <lastmod> tag indicating when it was last updated.
How to Submit an XML Sitemap to Google Search Console
Once a sitemap exists and is accessible at a public URL (commonly yoursite.com/sitemap.xml), submitting it to Google is a fairly straightforward process:
- Sign in to Google Search Console with the account associated with your verified website property.
- Select the correct property if you manage more than one site.
- Go to the Sitemaps section, found in the left-hand menu.
- Enter your sitemap's path — usually just sitemap.xml, since the domain itself is already tied to the verified property.
- Submit it, and Search Console will report back on whether it was read successfully, along with how many URLs were discovered.
- Check back periodically to review the status, since Search Console will flag errors if certain URLs in the sitemap have issues.
This process only needs to happen once for a static sitemap; for a properly maintained dynamic sitemap, Google will typically recrawl it periodically on its own once submitted.
XML Sitemap for Dynamic Websites
This is particularly relevant for businesses running custom web applications rather than a standard CMS — a common situation for larger or more specialized business websites. On a dynamic site, pages are generated from a database rather than existing as fixed files, which means the sitemap needs to reflect that same dynamic reality rather than being a static file someone manually updates.
From a development perspective, this generally means building the sitemap generation logic to pull directly from the same database driving the site itself — querying for all currently published, indexable content (blog posts, product listings, service pages, and so on), and excluding anything unpublished, deleted, or marked noindex.
A conceptual example, simplified for clarity:
php
<?php header("Content-Type: application/xml; charset=utf-8"); echo '<?xml version="1.0" encoding="UTF-8"?>'; echo '<urlset xmlns="http://www.sitemaps.org/schemas/sitemap/0.9">'; $pages = getPublishedPages(); // pulls only published, indexable, non-deleted pages foreach ($pages as $page) { echo '<url>'; echo '<loc>https://example.com/' . htmlspecialchars($page['slug']) . '</loc>'; echo '<lastmod>' . $page['updated_at'] . '</lastmod>'; echo '</url>'; } echo '</urlset>'; ?>The important practical details here: new pages get added to the sitemap automatically the moment they're published, without anyone manually editing a file. The lastmod value updates automatically whenever a page's content actually changes. Deleted or unpublished pages disappear from the sitemap automatically too, rather than lingering as broken entries. For larger sites, it's also common to split content into separate sitemaps by type — one for blog posts, one for product pages, and so on — with a sitemap index file referencing all of them together.
Common XML Sitemap Mistakes Businesses Should Avoid
A few mistakes that show up repeatedly in practice:
- Including non-canonical URLs, creating confusion about which version of a page is actually the intended one
- Including 404 or broken URLs, often left over after a page was deleted or moved without updating the sitemap
- Including noindex pages, sending a contradictory signal about whether a page should actually appear in search results
- Using incorrect or outdated URLs, particularly common after a site migration or URL structure change
- Failing to update a dynamic sitemap properly, so it quietly falls out of sync with the site's actual current content
- Inconsistent HTTPS or www usage, where the sitemap lists URLs in a different format than the site's actual canonical version
- Creating duplicate sitemap URLs, sometimes from multiple plugins or systems each generating their own version without anyone realizing
- Assuming a submitted sitemap guarantees indexing, when it's genuinely just a discovery aid, not a directive that forces a page into search results
How to Check Whether Your XML Sitemap Is Working
A few practical checks worth doing periodically:
Open the sitemap directly in a browser at yoursite.com/sitemap.xml and confirm it loads properly, rather than showing an error.
Check the HTTP status of the sitemap file itself, confirming it returns a proper 200 OK response rather than an error or unexpected redirect.
Verify XML validity — a malformed sitemap can be silently ignored or misread by search engines, so confirming it's properly structured XML matters.
Spot-check a handful of listed URLs to confirm they actually load correctly and aren't accidentally pointing to redirected or broken pages.
Review the Sitemaps section in Google Search Console, which reports how many URLs were successfully read from the sitemap and flags any errors it encountered.
Check indexing status separately, using Search Console's URL inspection tool or a site: search — remembering that sitemap submission and actual indexing are two different things worth verifying independently.
XML Sitemap Best Practices
A concise checklist worth keeping in mind:
- Include only canonical, indexable URLs
- Exclude redirects, 404s, noindex pages, and duplicate content
- Use accurate lastmod values where genuinely meaningful
- Keep the sitemap automatically updated on dynamic or frequently changing sites
- Split large sites into multiple sitemaps with a sitemap index if needed
- Submit the sitemap through Google Search Console and monitor its status
- Periodically verify the sitemap is accessible, valid, and accurate
- Don't treat sitemap submission as a substitute for good site structure and internal linking
Final Thoughts
An XML sitemap is a fairly small, unglamorous piece of a website's technical foundation, but it solves a real, specific problem — making sure search engines have a clear, reliable way to discover the pages you actually want found. It won't fix weak content, and it won't force pages into search results on its own. What it does is remove one genuine point of friction in the discovery process, particularly for larger, newer, or frequently changing websites, and that's a meaningful, worthwhile thing to get right, even if it rarely gets much attention until something's gone wrong.
If your website's pages aren't showing up in search the way you'd expect, checking whether the sitemap is present, accurate, and properly submitted is a reasonable, practical first step — alongside the broader technical and on-page factors it works alongside. We've covered related pieces of this picture in more detail in our articles on the difference between on-page and technical SEO and how internal linking helps search engines understand your website, both of which connect directly to how well a site's pages actually get discovered and understood.
If you'd like a proper look at your own site's technical SEO foundation, including its sitemap, get in touch with Software Solutions and we'll walk through it together.
Frequently Asked Questions
What is an XML sitemap? An XML sitemap is a structured file listing the URLs on a website that you want search engines to discover, helping them find pages more reliably than relying on crawling and internal links alone.
Does submitting an XML sitemap guarantee my pages will be indexed? No. A sitemap helps with discovery, but indexing still depends on content quality, technical factors, and a search engine's own evaluation of each page.
What should be excluded from an XML sitemap? Redirected URLs, 404 pages, noindex pages, duplicate URLs, and irrelevant parameter or filter URLs should generally be left out.
How often should an XML sitemap be updated? For dynamic or frequently changing websites, the sitemap should update automatically as content is added, changed, or removed. Static sites can update it manually whenever meaningful changes occur.
What's the difference between an XML sitemap and a robots.txt file? A robots.txt file tells search engines what they're allowed or not allowed to crawl. An XML sitemap tells them what you'd specifically like them to discover and consider indexing. They serve related but distinct purposes.
Do small business websites really need an XML sitemap? Smaller sites with few pages and strong internal linking may function reasonably well without one, but a sitemap is still a low-effort safeguard that helps ensure nothing gets missed, particularly as a site grows.
About the Author
Software Solutions is a web and software development company in India specializing in custom web development, business applications, website maintenance, and SEO-friendly web solutions.